Archive
LLM handling of programming language differences
LLMs are trained on the publicly available source code, with no consideration given to the programming language used. There is an implicit assumption that training on code written in X and Y, rather than just Y, produces an LLM that does a better job of generating code written in Y.
To what extent will the characteristics of the training data from language X source ‘leak’ into source code generated for language Y?
LLM source generation is a very new field and significant improvements are still being made to models and agent harnesses. This article lists some issues, and checks how a few models handle them.
It would be great to have lots of LLM generated code to measure, and there are a few collections of LLM generated code. However, reliably distinguishing human from LLM generated code is an open problem. A 2025 study of Python source generated by multiple LLMs found that it was not possible to reliably predict human/LLM authorship (which suggests that LLM source datasets collected using authorship prediction are likely to be unreliable). The characteristics of a dataset of individual functions are unlikely to have the same distribution as a dataset of complete programs.
Some language usage behaviours are the result of the widespread adoption of particular conventions, and from the program correctness perspective these differences are harmless (e.g., source indentation), while others are semantic differences that could produce different output.
While patterns caused by coding conventions might not change
program output, they can change its performance characteristics (e.g., larger functions can alter cache occupancy), and some of these patterns are input to mathematical models of program evolution, e.g., distribution of method size (in LOC) is a factor in modelling the percentage of methods containing no reported faults.
The plot below shows the percentage of C/C++ (same behavior) and Java functions/methods containing a given number of lines (data recently extracted using CodeQL’s variant analysis of 100 C/C++ and Java projects, with 1,094,911 C++ functions, 328,009 C functions and 4,506,326 Java methods; code+data):
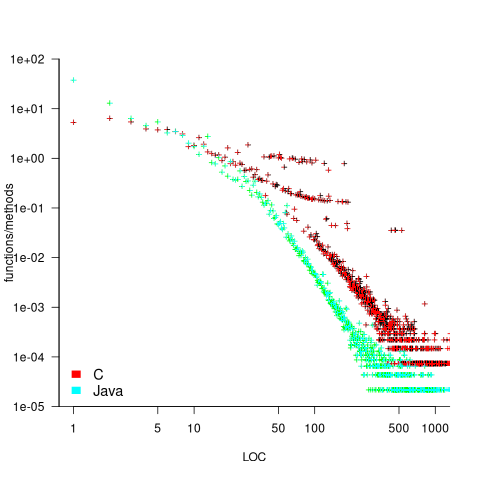
The large number of 1-line Java methods is assumed to be due to the widespread use of getters/setters. For the most common function/method sizes (i.e. 1 to 10 lines), have C and Java very different distributions, but follow a very similar power law for more than around 50 lines. Will LLM generate code contain this C/Java size difference, or will it have a completely different distribution (coding agents do seem to generate more code)?
Pre-object-oriented algorithmic languages can be classified into two families, those influenced by Fortran and those influenced by C.
In Fortran arrays are 1-based, while in C they are 0-based. The base-value for arrays is common knowledge, which LLMs handle. The more obscure differences, which rarely occur in source, are more likely to be overlooked.
Fortran and C have differences in operator precedence. The significant difference is the relative precedence of the unary not operator, and the binary equality/relational operators. The expression: ! x == y is equivalent to .not. (x == y) in Fortran, and equivalent to: (!x) == y in C. When asked to convert a C function containing the unbracketed form of the expression to Fortran, both Grok 4.6 and ChatGPT 5.5 note the different operator precedence and insert the appropriate parenthesis.
Both C and Python are popular languages with huge quantities of source publicly available. The token sequence: x < y == y, is parsed as: (x < y) == y in C, but in Python it is parsed as: (x < y) and (y == y). Both Grok and ChatGPT note the different operator precedence and insert the appropriate parenthesis.
There are a variety of differences between C and C++. However, source containing occurrences of all but two of them will produce a compile time error.
The following difference is known in compiler writer circles, and both Grok and ChatGPT note the different possible behaviors:
template_name < a , b > - 5 // equivalent to (template_name < a , b >) - 5) non_template_name < a , b > - 5 // equivalent to (non_template_name < a) , (b > - 5) |
The C/C++ difference that is much more likely to be encountered is the expression sizeof('a'), where C promotes the character 'a' to an int (which commonly has size 4; on DSP processors char often occupies the same number of bits as an int, giving both of them a size of 1), while C++ 'a' has type char (which is defined to have size 1).
There are sometimes behavior differences, for the same source, between versions of the same language specification. For instance, the following somewhat obscure difference between the C90, C99, and C11 language standards:
#include <stdio.h> #define M(U) sizeof(U"s"[0]) int main(void) { switch(M("")*2 //**/ 2 ) { case 1: printf("C90\n"); break; case 2: printf("C99\n"); break; case 8: printf("C11\n"); break; } } |
When asked what this program outputs, ChatGPT only considers C11, and 'corrects' itself after I pointed out the C90 lexical behavior. Grok only considers the latest standard, and when asked about producing other outputs, runs gcc with various -std options to find the other cases.
Both LLMs used (Grok 4.6 and ChatGPT 5.5) handled all the language differences I tried. Will cheaper to use coding agents, using LLMs containing an order of magnitude fewer parameters, be as effective at handling obscure differences? We will have to wait and see.
Source line length before coding agents
Will coding agent generated source code contain the same consistent patterns of behaviors that appear in human written source?
A brief analysis would suggest that the answer is: Yes. LLM training data is human written code, and coding agents are generating code to implement the functionality that developers would have otherwise implemented themselves.
Some coding patterns are driven by historical accidents, or at least appear to be. A line of code has to be visible on the display seen by the person writing it. Consequently, a line of source containing more characters that can be displayed on a line are likely to be rare. The plot below shows the number of C/C++ source lines containing a given number of characters in early 2000 (red) and 2026 (green), and the number of lines containing a given number of tokens in 2000 (blue), lines are fitted exponentials, and vertical grey lines at 80 and 120 characters (common default value used for tab characters; code+data):
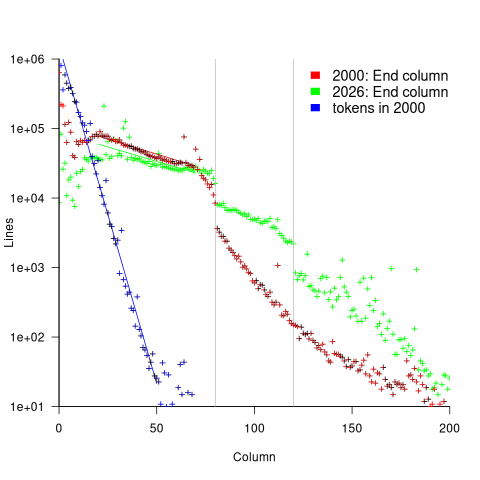
The dramatic drop in the number of lines of a given length, just below 80 characters, is consistent with the majority of character-based displays having lines containing 80 characters (the same as punched cards). A revolution in display technology happened between 2000 and 2026, namely CRTs were replaced by LCDs, significantly increasing possible display width. The decline in number of lines containing a given number of characters has decreased since 2000. In 2026, the 80 character line length break-point is less dramatic than in 2000, and the decline a lot less steep. Also, there appears to be a new break-point emerging at 120 characters; perhaps without LLMs the 80 character break-point would have gradually disappeared. While bit-mapped displays don’t have lines, existing practices live on and evolve.
The number of lines containing a given number of tokens, for the early 2000 measurements, decreases exponentially, with 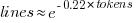 . Whitespace indentation adds characters, not tokens.
Most long lines are caused by indentation of the source code, e.g., indenting the body of an if-statement. Indentation is used to reduce the developer effort needed to understand statement clustering and sequencing.
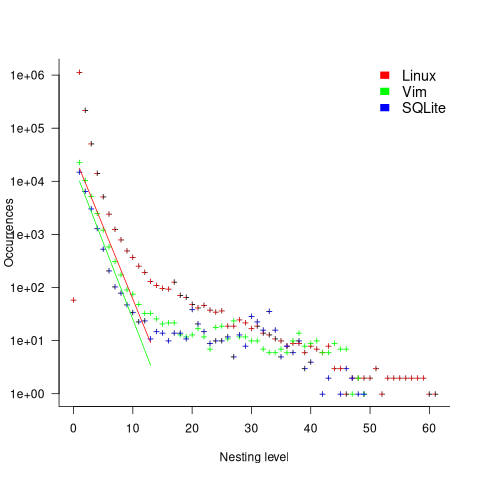
The plot below shows the number of if-statements occurring at a given nesting level, along with regression fits, of the form 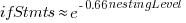 , to the 2026 Vim and SQLite data; the Linux data was better fitted by a power law (code+data):
Some of the reasons developers write deeply nested code include: the nested code accesses local variables that would be a hassle to pass as function arguments, creating a function would interrupt their train of thought.
Deep nesting is often cited as bad practice, along with the usual unsubstantiated claims about it being error-prone, or hard to understand, or whatever.
Coding agents indent code because the training data contains indented code, and because the generated source is likely to be looked at and modified by developers. Attention based LLMs include information on the position of the token on a line, so given the contents of the training data, coding agents are unlikely to generate lines containing more than 80 characters.
If a time is reached when most developers don’t look at agent created code (few look at the assembly code generated by compilers), its visual layout becomes irrelevant. There are cost savings to be made by not indenting or limiting nesting depth. Indentation increases coding agent costs by consuming more tokens. Creating a new function consumes more tokens that simply generating a deeper nesting level.
If a developer wants to see indented source, they can always use a pretty printer.
A coding agent can be told not to indent, but given their training data do they indent internally and then remove it, i.e., an increase in token usage? This is another question to the growing list of Mechanistic interpretability problems.
Project implementation time savings using coding agents
To what extent do the significant savings made from using coding agents reduce the total cost of creating a software system?
The SEA Data Warehouse dataset contains detailed records of time spent in various phases of safety critical projects. Just what is needed to estimate an answer to this question, at least for safety critical software.
The development of typical commercial software differs from safety critical software in the amount of effort that goes into requirements, design, documentation, and testing. While the safety critical people claim that it’s all about the processes they follow, there is no evidence to show that any process is better than another. What matters is that the process ensures that the requirements, design, documentation, and testing are good enough for the intended use of the software.
When producing code is cheap, teams looking to be paid to create software systems are going to have to add value by delivering the kind of reliability and all encompassing application support that safety critical software is intended to provide.
The plot below shows, for the 289 projects that spent more than 2-days Code phase, the fraction of time spent in the most common project phases, ordered by fraction spent in Code phase (code+data):
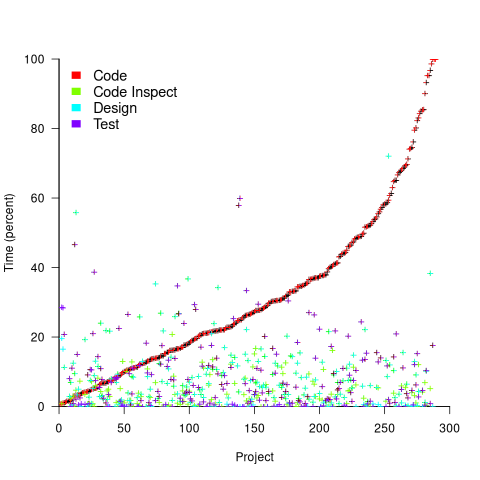
The average percentage of project time spent in the Code phase was 32% (does not include time spent in the Code review phase).
If we assume that coding agents reduce the time spent on coding by, say, 90%, and on all testing activities by, say, 50%, how much would total project time be reduced? The plot below shows, for the 289 projects, original project time (red) and estimated LLM project time (blue/green; code+data):
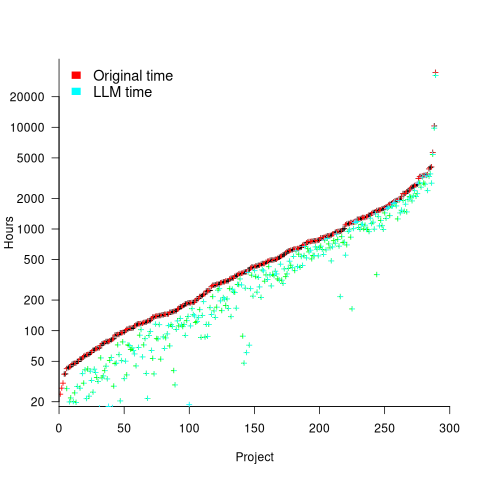
The general pattern visible is that as the number of project hours increases, the relative LLM saving shrinks. Around 10+ projects show substantial savings.
It’s possible that use of coding agents will increase the amount of time developers spend in the Code review phase (after any LLMs savings made in this phase). The 50% savings across all testing activities is very simplistic, and we will have to wait a few years for things to settle down and data to become available.
Around 10-15% of time is spent in Design, Design review, Design Inspection phases. Will LLMs save a significant amount of time for these phases, or should people continue to be hands-on for this work?
Experienced developers are well aware that coding agents have not removed the need for software developers. This post provided some data+analysis showing that developers are still needed, although the number of the people having this job title will decrease. Perhaps the software developer job title will not exist in 10-years, and this kind of work will be commonly known by another name.
Software effort estimation in 2026
It’s 2.5 years since my 2024 post summarizing what I knew about software effort estimation. For ongoing projects the role of estimation is as a planning tool, breaking down a large chunk of work into what are estimated to be small, well-defined, chunks. With two-thirds of estimates being within a factor of four (over or under) of the actuals, accuracy was not a primary goal.
The impact of coding agents capable of implementing these small tasks for peanuts is on developer staffing, not on the need for planning and breaking down work into connected small chunks.
Coding agents follow the specification they are given. Large, complicated programs will have large complicated specifications, which are likely to require a lot of human effort to create. For instance, the specification for the recent LLM generated C compiler
How long will it take to create a specification and how many iterations will be needed to create a good enough program? Estimation has not gone away, it has just moved upstream of the implementation. While specifications have existed millennia longer than software development, we are at the start of learning to use them to direct coding agents (the term vibe coding was created in February 2025). While logs of developer coding agent sessions are starting to be collected, it will take some years for patterns of practice to stabilize.
The process followed to estimate Function Points appears to be ideally placed to be extended to cover specification creation for coding agents.
Peanuts in bulk can be expensive. The novelty of much lower costs, when using coding agents, will soon wear off. Agent costs will become the new normal, which means there will be pressure to reduce them, and management will want estimates because the requirement to fill in boxes has not gone away.
Is agent token consumption purely a driven by the LLM(s) used and the selected configuration values? A recent study investigated the impact of the wording of the specification on the tokens spent by a selection of agents. The results showed that a specification containing bare user stories increased token spending by 30%. We will have to wait to find out whether the implications of this result (i.e., investing in more detailed user stories reduces token spending) replicates.
It would be very useful to have an estimate of likely token usage for a given specification, before any code is generated, or perhaps a real-time cost estimate during generation. One study found that current frontier models failed to accurately predict their own token usage (correlation of 0.39), humans predictions were equally poor.
Many projects don’t have a separate line item for testing costs, which often get bundled with implementation costs (the SEA Data Warehouse dataset separates out design/implementation/testing effort). Large projects may have people who work on integration and/or release testing.
When coding agents are used, testing is clearly a distinct piece of work separate from implementation. How effective is the specification used to generate the code at generating good enough tests? Current research is an extension of existing testing practices, rather than anything coding agent specific. A lot of existing research has focused on unit testing, and of course models have been fine-tuned for unit testing.
Implementation cost reductions have brought N-version programming into the realm of consideration for some projects.
Will the way developers work change to be like tradesmen who are hired to install a new fitted kitchen or bathroom? With developers installing new application functionality specified by the client. Perhaps some will be more like builders hired to make structural changes to a house, while others will do small jobs, like plumbers, electricians and carpet fitters.
As always, some researchers fail to move on when the world changes and continue to publish papers that use LLMs to estimate human task implementation time.
Recent Comments