Archive
LLM handling of programming language differences
LLMs are trained on the publicly available source code, with no consideration given to the programming language used. There is an implicit assumption that training on code written in X and Y, rather than just Y, produces an LLM that does a better job of generating code written in Y.
To what extent will the characteristics of the training data from language X source ‘leak’ into source code generated for language Y?
LLM source generation is a very new field and significant improvements are still being made to models and agent harnesses. This article lists some issues, and checks how a few models handle them.
It would be great to have lots of LLM generated code to measure, and there are a few collections of LLM generated code. However, reliably distinguishing human from LLM generated code is an open problem. A 2025 study of Python source generated by multiple LLMs found that it was not possible to reliably predict human/LLM authorship (which suggests that LLM source datasets collected using authorship prediction are likely to be unreliable). The characteristics of a dataset of individual functions are unlikely to have the same distribution as a dataset of complete programs.
Some language usage behaviours are the result of the widespread adoption of particular conventions, and from the program correctness perspective these differences are harmless (e.g., source indentation), while others are semantic differences that could produce different output.
While patterns caused by coding conventions might not change
program output, they can change its performance characteristics (e.g., larger functions can alter cache occupancy), and some of these patterns are input to mathematical models of program evolution, e.g., distribution of method size (in LOC) is a factor in modelling the percentage of methods containing no reported faults.
The plot below shows the percentage of C/C++ (same behavior) and Java functions/methods containing a given number of lines (data recently extracted using CodeQL’s variant analysis of 100 C/C++ and Java projects, with 1,094,911 C++ functions, 328,009 C functions and 4,506,326 Java methods; code+data):
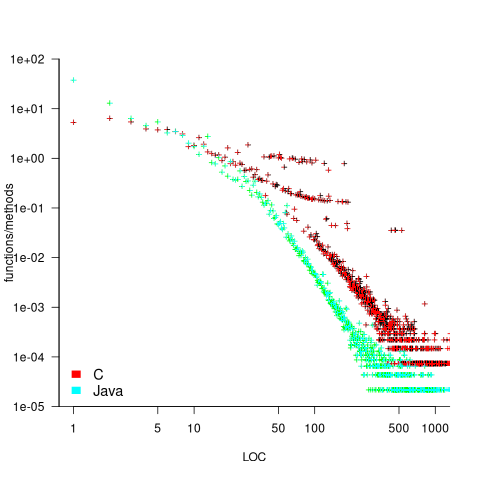
The large number of 1-line Java methods is assumed to be due to the widespread use of getters/setters. For the most common function/method sizes (i.e. 1 to 10 lines), have C and Java very different distributions, but follow a very similar power law for more than around 50 lines. Will LLM generate code contain this C/Java size difference, or will it have a completely different distribution (coding agents do seem to generate more code)?
Pre-object-oriented algorithmic languages can be classified into two families, those influenced by Fortran and those influenced by C.
In Fortran arrays are 1-based, while in C they are 0-based. The base-value for arrays is common knowledge, which LLMs handle. The more obscure differences, which rarely occur in source, are more likely to be overlooked.
Fortran and C have differences in operator precedence. The significant difference is the relative precedence of the unary not operator, and the binary equality/relational operators. The expression: ! x == y is equivalent to .not. (x == y) in Fortran, and equivalent to: (!x) == y in C. When asked to convert a C function containing the unbracketed form of the expression to Fortran, both Grok 4.6 and ChatGPT 5.5 note the different operator precedence and insert the appropriate parenthesis.
Both C and Python are popular languages with huge quantities of source publicly available. The token sequence: x < y == y, is parsed as: (x < y) == y in C, but in Python it is parsed as: (x < y) and (y == y). Both Grok and ChatGPT note the different operator precedence and insert the appropriate parenthesis.
There are a variety of differences between C and C++. However, source containing occurrences of all but two of them will produce a compile time error.
The following difference is known in compiler writer circles, and both Grok and ChatGPT note the different possible behaviors:
template_name < a , b > - 5 // equivalent to (template_name < a , b >) - 5) non_template_name < a , b > - 5 // equivalent to (non_template_name < a) , (b > - 5) |
The C/C++ difference that is much more likely to be encountered is the expression sizeof('a'), where C promotes the character 'a' to an int (which commonly has size 4; on DSP processors char often occupies the same number of bits as an int, giving both of them a size of 1), while C++ 'a' has type char (which is defined to have size 1).
There are sometimes behavior differences, for the same source, between versions of the same language specification. For instance, the following somewhat obscure difference between the C90, C99, and C11 language standards:
#include <stdio.h> #define M(U) sizeof(U"s"[0]) int main(void) { switch(M("")*2 //**/ 2 ) { case 1: printf("C90\n"); break; case 2: printf("C99\n"); break; case 8: printf("C11\n"); break; } } |
When asked what this program outputs, ChatGPT only considers C11, and 'corrects' itself after I pointed out the C90 lexical behavior. Grok only considers the latest standard, and when asked about producing other outputs, runs gcc with various -std options to find the other cases.
Both LLMs used (Grok 4.6 and ChatGPT 5.5) handled all the language differences I tried. Will cheaper to use coding agents, using LLMs containing an order of magnitude fewer parameters, be as effective at handling obscure differences? We will have to wait and see.
What language was an executable originally written in?
Apple have recently added an unusual requirement to the iPhone developer agreement “Applications must be originally written in Objective-C, C, C++, or JavaScript …”. As has been pointed out elsewhere the real purpose is stop third party’s from acquiring any control over application development on Apple’s products; the banning of other languages is presumably regarded as acceptable collateral damage.
Is it possible to tell by analyzing an executable what language it was originally written in?
There are two ways in which executables contain source language ‘signatures’. Detecting these signatures requires knowledge of specific compiler behavior, i.e., a database of information about the behavior of compilers capable of creating the executables is needed.
Runtime library. Most compilers make use of a language specific runtime library, rather than generating inline code for some kinds of functionality. For instance, setjmp/longjmp in C and vtables in C++.
The presence of a known C runtime library does not guarantee that the application was originally written in C; it could have been written in Java and converted to C source.
The absence of a known C runtime library could mean that the source was compiled by a C compiler using a runtime system unknown to the analyzer.
The presence of a known Java, for instance, runtime library would suggest that the original source contained some Java. This kind of analysis would obviously require that the runtime library database not restrict itself to the ‘C’ languages.
Compiler behavior patterns. There is usually more than one way in which a source language construct can be translated to machine code and a compiler has to pick one of them. The perfect optimizing compiler would always make the optimal choice, but real compilers follow a fixed pattern of code generation for at least some language constructs (e.g., initialization of registers on function entry).
The presence of known code patterns in an executable is evidence that a particular compiler has been used; how much depends on the likelihood it could have been generated by other means and how many other patterns suggest the same compiler. In the case of the GNU Compiler Collection the source language might also be Fortran, Java or Ada; I don’t know enough about the behavior of GCC to provide an informed estimate of whether it is possible to recognize the source language from the translated form of constructs shared by several languages, I suspect not.
The fact that an executable can be decompiled to C is not a guarantee that it was originally written in C.
Some languages support source language constructs whose corresponding machine code is unlikely to ever be generated by source from another language. The Fortran computed goto allows constructs to be written that have no equivalent in the other languages supported by GCC (none of them allow statement labels appearing in a multi-way jump to appear before the jump test):
10 I=I+1 20 J=J+1 goto (10, 20, 30, 40) J 30 I=I+3 40 I=I*2 |
The presence of a compiled form of this kind of construct in the executable would be very suggestive of Fortran source.
Apple are famously paranoid and control freakery. It will be very interesting to see what level of compliance checking they decide to perform on executables submitted to the App Store.
On another note: What does “originally written” mean? For instance, many of the mathematical functions (e.g., sine, log, gamma, etc) contained in R were originally written in Fortran and translated to C for use in R; this C source is what is now maintained. Does this historical implementation decision mean that R cannot be legally ported to the iPhone?
Recent Comments