Archive
Programming language choice is becoming a build option
What significant problems do high-level programming languages solve in a world of coding agents?
The original rationale for using high-level languages was to reduce the cost of porting existing software to different platforms. In a coding agent world, this is a benefit for those interested in having their software run on more than one platform. Is it a worthwhile benefit for those running on just iOS and Android (Shopify recently switched to a common codebase in React Native)? A general answer to this question will have to wait until things have settled down, some years from now.
Some software systems have configuration options that are selected at compile time. Having coding agents generate all possible option configurations is only practical when there are only a few possible combinations. The Linux kernel contains around 15,000 options, and while many of the  possible option combinations are unrealistic, just 243,323 combinations produces a huge variety of executable programs. The source code approach is the only workable approach when many compiler time options need to be supported.
Existing practice is that program source code is written in a high level language, which is then translated to an executable form. Generating source in the programming language(s) being actively used enables coding agents to be seamlessly integrated into existing practices.
In specification based programming, English (or another human language) is the language used to create software. The actual programming language used when generating source code is not yet irrelevant.
Various kinds of activities are reviewed during the development of a software system. These include: requirements review, design review, code review, test review, and acceptance review.
Source code is needed for code review, which is frequently talked about but infrequently performed (an analysis of evidence; see section 6.6.1 for a summary of practices). Code review is a great mechanism for synchronizing practices within a team, training new developers and generally keeping team members up to date with what others are doing. These are benefits that apply when software is written by people. When source is generated by a coding agent, why do people need to review it? The reasons I have heard involve issues covered during requirements and design reviews. Another coding agent might check the code looking for mistakes, and this could be labelled as a (non-human) code review.
If the generated source is not going to be read by people, does it matter which programming language is used to generated it?
Coding agents require source code for training, and this is available in a variety of programming languages. Quantity of source code training data has a significant impact on LLM performance. Generating source in the language most likely to elicit the best coding agent performance is the obvious answer.
Choice of programming language is sometimes driven by current fashions, happenstance or a particular belief system. For instance, the conversion of existing non-Rust source to Rust is driven by the current fashionably status of that language, along with the effectiveness and low cost of coding agents.
Programming languages choice is evolving in to being a configuration option.
I’m sure that eventually somebody will convert the Linux kernel to Cobol and build a running system. As a start, I used the Devin coding agent to convert the contents of the kernel init directory to Cobol source and Fortran source. Both sets of source compile, but don’t link against any other kernel object files.
Before coding agents hackers were content to create their own new Linux distribution. To be leading edge in the future, a hacker will need to translate the Linux kernel and/or distribution to a language of their own creation (LLMs are now building compilers).
Single-handedly creating/implementing a language and using it to implement an operating system used to be a niche activity. First released in 2005, Terry A. Davis single-handedly wrote TempleOS in a language he created and implemented called HolyC, driven by a revelation from God. In the coming years, I expect to see many of these belief driven projects.
Growth and survival of gcc options and processor support
Like any actively maintained software, compilers get more complicated over time. Languages are still evolving, and options are added to control the support for features. New code optimizations are added, which don’t always work perfectly, and options are added to enable/disable them. New ways of combining object code and libraries are invented, and new options are added to allow the desired combination to be selected.
The web pages summarizing the options for gcc, for the 96 versions between 2.95.2 and 9.1 have a consistent format; which means they are easily scrapped. The following plot shows the number of options relating to various components of the compiler, for these versions (code+data):
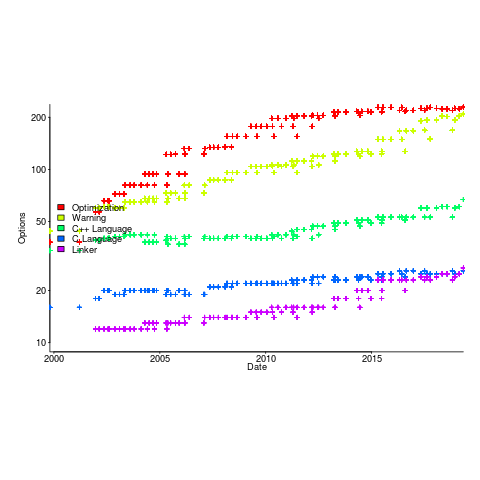
The total number of options grew from 632 to 2,477. The number of new optimizations, or at least the options supporting them, appears to be leveling off, but the number of new warnings continues to increase (ah, the good ol’ days, when -Wall covered everything).
The last phase of a compiler is code generation, and production compilers are generally structured to enable new processors to be supported by plugging in an appropriate code generator; since version 2.95.2, gcc has supported 80 code generators.
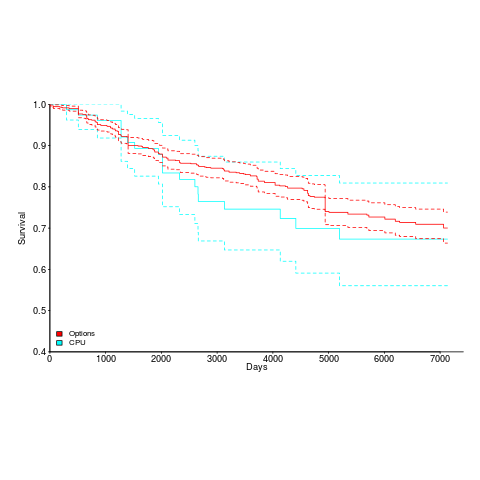
What can be added can be removed. The plot below shows the survival curve of gcc support for processors (80 supported cpus, with support for 20 removed up to release 9.1), and non-processor specific options (there have been 1,091 such options, with 214 removed up to release 9.1); the dotted lines are 95% confidence internals.
Recent Comments