Archive
Non-trivial data analysis using coding agents
Users cause faults in that they select the code that is executed (via the application functionality used), and provide the input that triggers the coding mistakes. Some application functionality is rarely used, while other functionality is often used. Can we go as far as to say that 20% of functionality is used 80% of the time?
The paper Are 20% of Files Responsible for 80% of Defects?, by N. Walkinshaw and L. Minku sounds like it might provide evidence to help validate the application usage assumption. The authors collected data on 100 GitHub projects, recording the files modified to fix a reported fault, plus various source code metrics. Their analysis looked for a correlation between the number of fault related fixes applied to a file and its source metrics. They did not find meaningful correlations, and that the commonly cited 80/20 split is somewhat fuzzy in practice.
I emailed the authors after the paper was published in 2018, to explain my interpretation of the 80/20 rule, i.e., driven by commonly executed code. The authors said they wanted to take the work further and were interested in exploring this alternative explanation. Researcher projects need funding, which takes time and effort to acquire, in the meantime COVID and then LLMs arrived.
Clustering a program’s source files by functionality, and then finding correlations between these clusters and fault driven fixes would once have required lots of work, and been a great PhD project. Now we have coding agents doing PhD level work in various fields. Perhaps an agent can do the heavy lifting of clustering the source files. Trusting one agent’s analysis would be naive (an analysis of one dataset by 29 independent human teams produced a surprisingly wide variety of conclusions), and the following analysis uses Claude Opus 5.5 (conversation here) and Devin (conversation here).
The paper analysed a version of each project in 2018, and the associated dataset includes the GitHub hash needed to download the corresponding snapshot of each project repo, e.g.,
https://github.com/buildbot/buildbot/archive/62ef53c36dd1d8a663f62ed4301a282a53b96d23.zip
A few Python and Java projects were downloaded as test cases. LLM performance is likely to be the strongest for these languages because of the quantity of training data available.
Not having any domain knowledge for the projects, I chose two reasonable sounding clustering factors: a description of the functionality implemented by the code contained in a file and the file’s ‘call-graph’. The first instruction give to the agent was:
The attached zip file contains a 2018 version of the buildbot Continuous Integration Framework written in python. Create a csv file containing each python file, F, one per row. Describe the application functionality implemented by the code in the file, F, and list all the other files that contain one or more functions that are called by a function in the file F. |
followed by the instruction:
Create a hierarchy of file clusters, based on the functionality they implement and use. |
The file/fault information for all the projects is contained in loc_churn_defects.csv. I’m sure the agent could have extracted the rows specific to each project, but I wanted to look at each project’s data first (old habits die hard; I also did the FpLOC calculation, got it wrong the first time, Claude pointed out my mistake and corrected it!).
The column FpLOC in the attached csv file lists the number of faults fixed per line in the python file listed in the corresponding File column. To what extent are files with high FpLOC clustered together and files with a low FpLOC clustered together. |
Both agents agreed that while there was some correlation between faults and fixes, it was at best mild. Both pointed out that file age is likely to be an important factor (i.e., more faults fixed in older files), and that adding this information could improve the correlation being sought.
The agents both took around 15 minutes elapsed time per project. The Devin chain-of-thought was interesting, while Claude was mostly uninformative while working.
Rather than spend time looking at the csv files produced (available via the conversation links above), and the summary analysis given after each question, I got the agents to write a paper:
Write a paper that describes the techniques used to describe each file, the hierarchical clustering algorithm, followed by the results of the investigating to find a connection between fault fixed and clustering. Suggest factors that limit the accuracy of the analysis and what could be done to gain a greater understanding of the connection between files and fixed faults |
The Claude Opus report was rather poor (just one graph; perhaps there is a data analysis toggle that needs to be set), while the Devin report was rather good (interesting graphs and analysis).
Without information on the age of the files, a very important factor, this dataset is not sufficient to say anything reliable about a possible 20/80 split.
Both Clause Opus 5.5 and Devlin performed very well. When doing research for real I would want more chain-of-thought, both to gain confidence about the final answer and to read about possible new ideas. The chain-of-thought provided by Chinese models makes them my first choice for building mathematical models. I need to experiment with the Chinese coding agents.
Unique bytes in a sliding window as a file content signature
I was at a workshop a few months ago where a speaker pointed out a useful technique for spotting whether a file contains compressed data, e.g., a virus hidden in a script by compressing it to look like a jumble of numbers. Compressed data contains a uniform distribution of byte values (after all, compression is achieved by reducing apparent information content), your mileage may vary between compression techniques. The thought struck me that it would only take a minute to knock up an R script to check out this claim (my use of R is starting to branch out into solving certain kinds of general coding problems) and here it is:
window_width=256  # if this is less than 256 divisor has to change in call to plot

plot_unique=function(filename)
{
t=readBin(filename, what="raw", n=1e7)

# Sliding the window over every point is too much overhead
cnt_points=seq(1, length(t)-window_width, 5)

u=sapply(cnt_points, function(X) length(unique(t[X:(X+window_width)])))
plot(u/256, type="l", xlab="Offset", ylab="Fraction Unique", las=1)

return(u)
}

dummy=plot_unique("http://shape-of-code.com/2013/05/17/preferential-attachment-applied-to-frequency-of-accessing-a-variable/")

dummy=plot_unique("http://www.shape-of-code.com/R_code/requirements.tgz") |
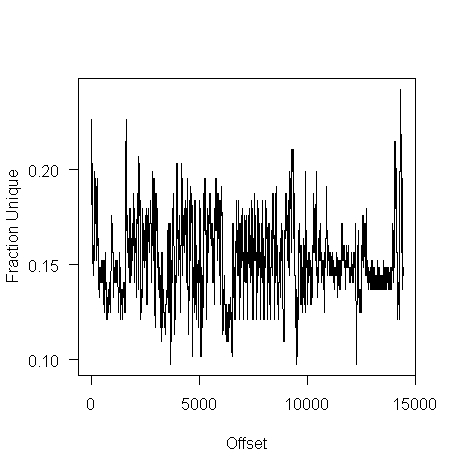
The unique bytes per window (256 bytes wide) of a HTML file has a mean around 15% (sd 2):
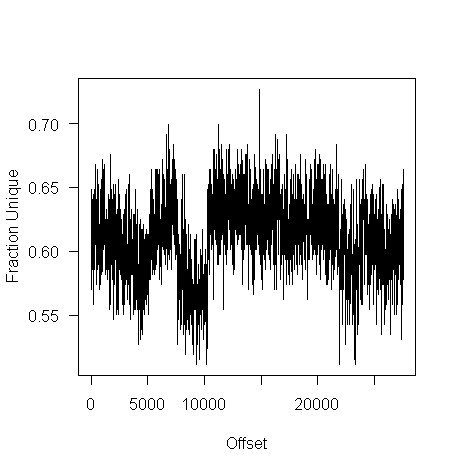
while for a tgz file the mean is 61% (sd 2.9):
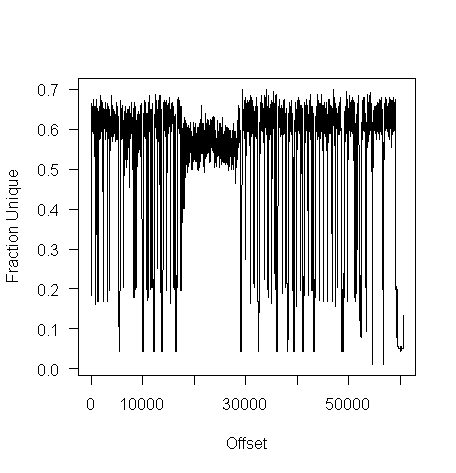
I don’t have any scripts containing a virus, but I do have a pdf containing lots of figures (are viruses hidden in pieces all all together?):
Do let me know if you find any interesting ‘unique byte’ signatures for file contents.
Recent Comments