Archive
Finding and choosing a hackathon to attend
Lots of developers seem to be interested in Hackathons but are not sure where to find out about them or what’s involved. This is part one of a summary of what I know about hackathons, based on a couple of years of going to them (mostly in and around London, my participation was sporadic until last year); the next article will offer some suggestions for what to do at a hackathon.
Hackathons-and-Jams UK is a great source of information about London based events; its a group on meetup.com which is the site to find out about out-of-work computer related get togethers; some of the other meetup groups that host events include: Data Science London, DataKind UK and Microservices Hackathon.
Eventbrite is often used by event organizers for attendee sign-up and searching this site using the obvious keywords is worthwhile.
The UK Hackspace Foundation lists more local groups meeting on a regular basis, an some hold hackathons.
Now you have a list of forthcoming events, which ones are worth attending (assuming a place is free; this year’s Battlehack ‘sold-out’ in six seconds)? I choose events based on how interesting they look and given a choice prefer those where I will be more relaxed (e.g., likely to have a comfortable place to sit, reasonable food and no noise) and much prefer 24 hr hacks (which usually start Saturday and finish Sunday); evening events are over almost before they have started. Events can be roughly classified as follows:
- Data driven: sponsors provide lots of data relating to a topic, or access to an API, and people have to use this to create something,
- Create anything: completely open-ended, as long as you make use of one of the sponsor’s API in some form,
- Create anything in hardware: a hardware hack essentially boils down to hanging peripherals off a single board computer and making something happen.
I cannot give you any useful advice about what interests you (apart from suggesting that you ignore details of what the actual prizes are, just have fun and aim to produce something that wows the crowd), but I can provide a few tips on evaluating venues.
My top two venues are The Hub Westminster (very comfy seats, a great atmosphere, plenty of local shops and food often good {but Pret does get tedious}) and Level 39 at Canary Wharf (fantastic food and great views).
The venue I try to avoid is the Google Campus, a 1960s bunker packed with solid wooden furniture to deform your body and numb your behind; a very low cost venue that Google are happy to let startups to use for almost nothing in some cases.
In general events held in company/university canteens will be uncomfortable places to hack (these places are designed to get people to leave after they have eaten) and often have WiFi that cannot support too many users at the same time.
Hackathons are generally free; non-free ones are treated with suspicion (but some will return your registration fee when you turn up, a way of ensuring people will only book if they really plan to attend; it not unusual for 50% of those registered not to show up on the day). The deal is that you use the sponsors’ API (and so become familiar with their product) and they feed and water you.
Generally you get to keep copyright and any IP, although posting the code to sites such as Github is encouraged. Some financial services hacks have terms & conditions that require you to sign over your soul. Its your soul, your call.
Semantic vs phonetic similarity for word pairs: a weekend investigation
The Computational Semantics hackathon was one of the events I attended last weekend. Most if the suggested problems either looked like they could not reasonably be done in a weekend (it ran 10:00-17:00 on both days, I know academics hacks) or were uninspiring coding problems. Chatting to some of the academics present threw up an interesting idea that involved comparing word pair semantic and phonetic similarity (I have written about my interest in sounds-like and source code identifiers).
Team Semantic-sounds consisted of Pavel and yours truly (code and data).
The linguists I chatted to seemed to think that there would be a lot of word pairs that sounded alike and were semantically similar; I did not succeed it getting any of them to put a percentage to “a lot”. From the human communication point of view, words that both sound alike and have a similar meaning are likely to be confused with each other; should such pairs come into existence they are likely to quickly disappear, at least if the words are in common usage. Sound symbolism related issues got mentioned several times, but we did not have any data to check out the academic enthusiasm.
One of the datasets supplied by the organizers was word semantic similarity data extracted from the Google news corpus. The similarity measure is based on similarity of occurrence, e.g., the two sentences “I like licking ice-cream” and “I like eating ice-cream” suggest a degree of semantic similarity between the words licking and eating; given enough sentences containing licking and eating there are clever ways of calculating a value that can be viewed as a measure of word similarity.
The data contained 72,000+ words, giving a possible half a billion pairs (most having zero similarity). To prune this down a bit we took, for each word, the 150 other words that were most similar to it, giving around 10 million word pairs. Each word was converted to a phoneme sequence and a similarity distance calculated for each pair of phoneme sequences (which we called phonetic distance and claimed it was a measure of how similar the words sounded to each other).
The list of word pairs with high semantic/phonetic similarity was very noisy, with lots of pairs containing the same base word in plural, past tense or some other form, e.g., billion and billions. A Porter stemmer was used to remove all pairs where the words shared the same stem, reducing the list to 2.5 million pairs. Most of the noise now came from differences in British/American spelling. We removed all word pairs that contained a word that was not in the list of words that occurred in the common subset of the British and American dictionaries used by aspell; this reduced the list to half a million pairs.
The output contained some interesting pairs, including: faultless/flawless, astonishingly/astoundingly, abysmal/dismal and elusive/illusive. These look like rarely used words to me (not enough time to add in word frequency counts).
Some pairs had surprisingly low similarity, e.g., artifact/artefact (the British/American spelling equality idea has a far from perfect implementation). Is this lower than expected semantic similarity because there is a noticeable British/American usage difference? An idea for a future hack.
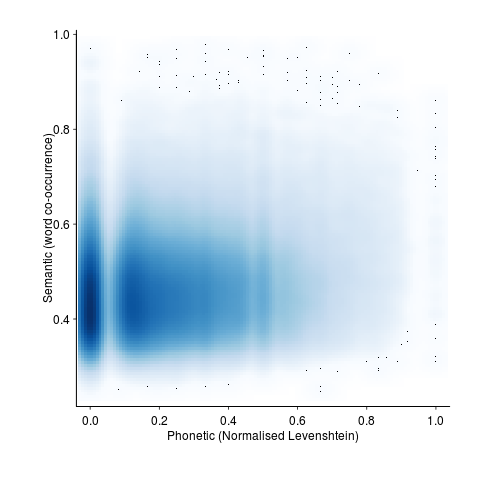
A smoothed scatter plot of semantic vs phonetic similarity (for the most filtered pair list) shows lots of semantically similar pairs that don’t sound alike, but a few that do (I suspect that most of these are noise that better stemming and spell checking will filter out). The following uses Levenshtein distance for phoneme similarity, normalised by the maximum distance for a given phoneme sequence with all phoneme differences having equal weight:
and using Jaro-Winkler distance (an alternative distance metric that is faster to calculate):
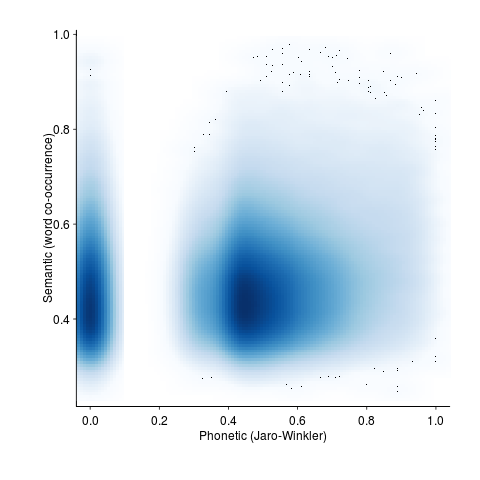
The empty band at low phonetic similarity is an artifact of the data being quantized (i.e., words contain a small number of components).
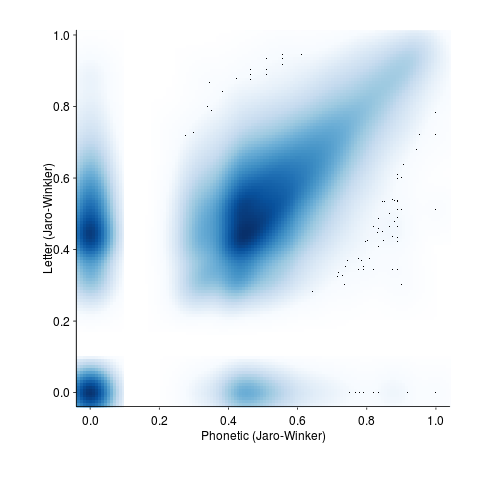
Is it worth going to the trouble of comparing phoneme sequences? Would comparing letter sequences be just as good? The following plot shows word pair letter distance vs phonetic similarity distance (there is a noticeable amount of off-diagonal data, i.e., for some pairs letter/phoneme differences are large):
Its always good to have some numbers to go with graphical data. The following is the number of pairs having a given phonetic similarity (remember the starting point was the top 150 most semantically similar pairs). The spikes are cause by the discrete nature of word components.
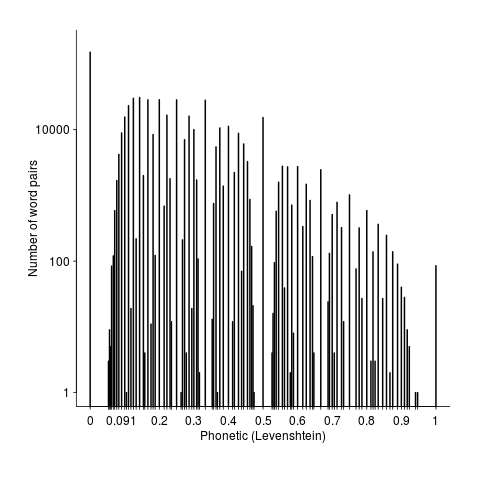
Squinting at the above it is possible to see an exponential decline as phonetic word similarity increases. It would be interesting to have enough data to display a meaningful 3D plot, perhaps a plane can be fitted (with a log scale on the z-axis).
Rather than using the Google news corpus data as the basis of word pair semantic similarity we could have used the synonym sets from Wordnet. This rather obvious idea did not occur to me until later Saturday and there was no time to investigate. How did the small number of people who created the Wordnet data come up with lists of synonyms? If they simply thought very hard they might have been subject to the availability bias, preferentially producing lists of synonyms that contained many words that sounded alike because those that did not sound alike were less likely to be recalled. Another interesting idea to check out at another hack.
It was an interesting hack and as often happens more new questions were raised than were answered.
A disheartening Space Apps hackathon
Every hackathon has its share of crazies, fortunately they rarely achieve sufficient critical mass to bother anybody else, generally wandering harmlessly around the venue. Hackathons involving outer space attracts crazies in droves and much of the first day is spent with everybody floating around in zero gravity.
This morning I stopped by the NASA SpaceApp hackathon in London to pick up my pass, say hi to a few people I knew were going and let them know I would be back later. A computational semantics hackathon was happening a few miles away, but finishing for the day at five (I know, academic hackathons). My plan was do interesting language analysis stuff, giving the crazies plenty of time to save the world (and then leave), before I returned to spend the rest of the weekend hacking on something space’ish.
The computational semantics hack was as interesting as it promised to be and I’m returning to it tomorrow (not the original plan).
I returned to the SpaceApp hack to find that while most of the crazies had gone, a lot of developers had also left. Had the crazies caused those with a firmer grip on reality to flee to the hills? The lack of coffee (yes, I did check several times that there were no plans to supply any coffee for the duration) and the wifi not being able to support everybody could not have helped. The few developers left (a fare few engineers, designers and ‘ideas’ people were still there) seemed to have been reduced to nibbling away at uninteresting bits (to me at least) of big problems. I left disheartened.
I think that part of the reason that non-crazies have trouble connecting with NASA’s proposed plans is that it is hard to tell the difference between NASA and the crazies. NASA’s mission has always been about politics first and science second. First as a means of boosting the US image around the world (the moon landing years) and then as a means of pork-barrel funding for favored politicians. To keep serious funding rolling in NASA has to ignite the public imagination. Fortunately for them the public is not very good at working out the economics of the proposed ventures (e.g., Google search on economics of asteroid mining to find plenty of articles exposing the economics flaws of this proposal).
While I am happy for the US taxpayer to funding NASA to do interesting space stuff and share it with the rest of the world, I do wish they could do it in a way that made technical and economic sense (I have no problem with them feeding the crazies, who have as much right to enjoy hackathons as the rest of us).
Been invaded by mysterious sounds? You need SoundHound
Team SoundHound (Gary, Pavel and yours truly) were at the Intel Hardware Hackathon last weekend. Hardware hacks are about the peripherals that are available on the day; I grabbed one of everything and we all sat down to play with them and come up with a great gadget to build. At an Intel sponsored event the computers are obviously Galileo and Edison (which is what we ended up using).
The Intel guys had a very fixed idea about how the hackathon was to run and specified that eight projects had to be proposed and selected (by everybody present) on the Friday night and that these would be worked on over the weekend (but we were allowed to change the idea; the logic escaped me). I proposed a vibration detection project to measure the impact of passing vehicles on houses next to busy roads. Nobody on what was to become SoundHound thought this was a great idea, but it was the only idea we had and there was nothing stopping us radically changing our mind over the weekend.
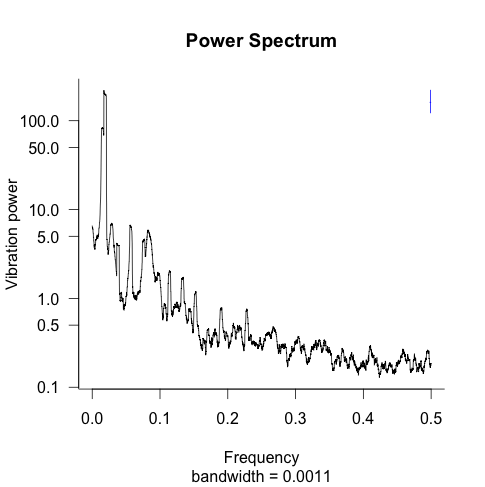
Vehicles generate sound which we can hear, but buildings are damaged by the lower frequency vibrations that we sometimes feel but don’t usually hear. A microphone would be useless, what was needed was a vibration sensor and a packet of piezo vibration sensors, the SEN-09198, was provided. We did not have any amplifiers to boost the signal, so the sensors were wired directly onto the signal pins; this meant that the dynamic range of the signal was about 50 times smaller than the input could handle and our test vibrations were created by banging on the table on which the sensor sat (power spectrum of me doing just that below).
We worked away on the vehicle vibration idea waiting for something better to come along. Some household appliances contain motors that cause them to vibrate, perhaps we could detect these vibrations. The use case here was a fridge next to a wall transmitting vibration into another room which then generated a hard to pin-down noise in that room. Around this time it occurred to us that a ghost detector (everybody knows that walls vibrate when ghosts travel through them) might be a bigger market, after all occult books sell well.
IBM were an event sponsor and had people on-hand to help us set up and use Bluemix, their cloud offering. The Edison board was communicating with our laptops via wifi and this got rerouted so the data was sent to IBM’s cloud storage. Collecting everybodies vibration data meant we could do pattern matching on the power spectrum of the vibration to identify candidates for the device most likely to be generating it (whether the vibration characteristics of different devices is sufficiently different for the pattern matching to be able to distinguish them at some useful level is another matter; I imagine that the shape of a fridge causes its vibration to modulate slightly from the frequency of the local electricity supply).
One of the problems of producing a working demo at a hackathon is being held to a much higher standard of reality. Teams whose output is slideware illustrating the tenuous connection its members have to reality don’t seem to have any trouble getting unquestioning agreement that anything they propose will just work. We were asked how we would obtain the vibration data for different household devices, against which the customer data could be compared; a marketing type capable of convincingly talking about our crowd source solution would have been useful.
Late Saturday afternoon saw team SoundHound out on the streets measuring vehicle vibration. Unfortunately large lorries traveling at speed are thin on the ground in central London, also guys standing next to a laptop with wires attached to something on the ground filming everything that went past had the effect of causing drivers to slow down to low vibration speeds (rather than speeding up to get away from us).
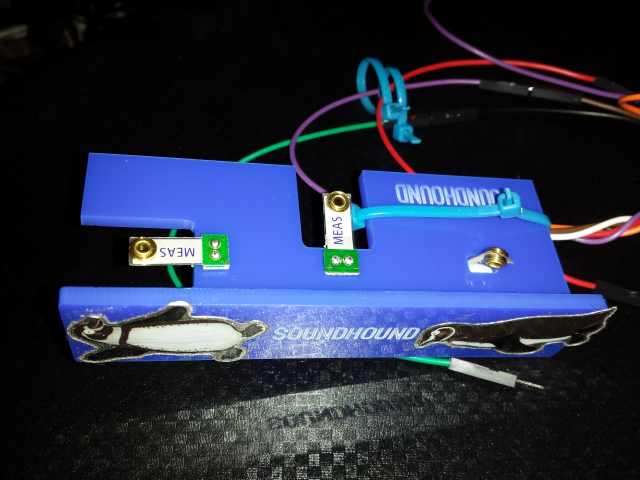
Perhaps we should have gone with the ghost detector sale pitch. The cloud data storage could have been rebranded as The Ethereum data matrix and flashing leds added to the hand-held sensor (the penguins below send the wrong message).
If it is possible to distinguish home appliances based on their vibration characteristics, and a database is created, there is an opportunity for salesmen to systematically check each house/flat ‘listening’ for appliances that are close to failing (motors vibrate more as they wear out): “Hello Sir, your fridge/boiler/air-conditioning is getting old and this week we have a special offer on replacements…”.
The picture below shows our 3-axis vibration sensor (plastic mounting/vibration interface laser cut by Elen from the FabLab, who do brown bag lunch and learn sessions if you are ever in central London). Two axis would probably been enough, and maybe even one, but we had the sensors and wanted to impress.
Long tail licensing
Team ‘Long Tail Licensing’ (Richard, Pavel, Gary and yours truly) took part in the Fintech startupbootcamp hackathon at the weekend.
As the team name suggests the plan was to implement a system of payment and licensing for products in the long tail, i.e., a large number of low value products. Paypal is good for long tail payment but does not provide a way for third parties to verify that a transaction has occurred (in fact Paypal does its best to keep transactions secret from everybody except those directly involved).
Our example use case was licensing of individual Github repositories. Most of today’s 3.4 million developers with accounts on Github would rather add more features to their code than try to sell it; the 16.7 million repositories definitely qualifies as a long tail of low value products (i.e., under £100). Yes, Paypal could be (and is) used as a method of obtaining payment, but there is no friction-free method for handling licensing (e.g., providing proof of licensing to third parties).
Long Tail Licensing’s implementation used cryptocurrency for both payment and proof of licensing (by storing license information in the blockchain). For the hackathon we set up out own private Bitcoin blockchain to act as a test rig, supply fast mining and provide near instantaneous response.
To use Long Term Licensing a developer creates the file .cryptolicense in the top level directory of their repo; this file contain information on the amount to pay, cryptocurrency account details and text of licensing terms. A link in the README.md file points at our server, which validates the .cryptocurrency file and sets up a payment transaction from the licensee’s Bitcoin wallet; the licensee confirms the transaction and the payment is made.
The developer’s chosen license information is included in the transactions blockchain, providing the paperwork that third-parties can view to verify what has been licensed. This licensing information could be in plain text or use public key encryption to restrict who can read it (e.g., eBay could publish a public key that third parties could encrypt information so that only eBay’s compliance department could read it).
The implementation code includes links to private servers and other stuff that it should not be be; hackathon code is rarely written with security in mind. So those involved would rather it not be pushed to Github (perhaps it will get tidied up and made suitable for public consumption at a later date).
We did not win any of the prizes :-(. Well done to Manoj (a frequent hackathon collaborator) and his team for winning the $100k of Google cloud time prize.
Top secret free information
I may or may not have been at a top secret hackathon at the weekend.
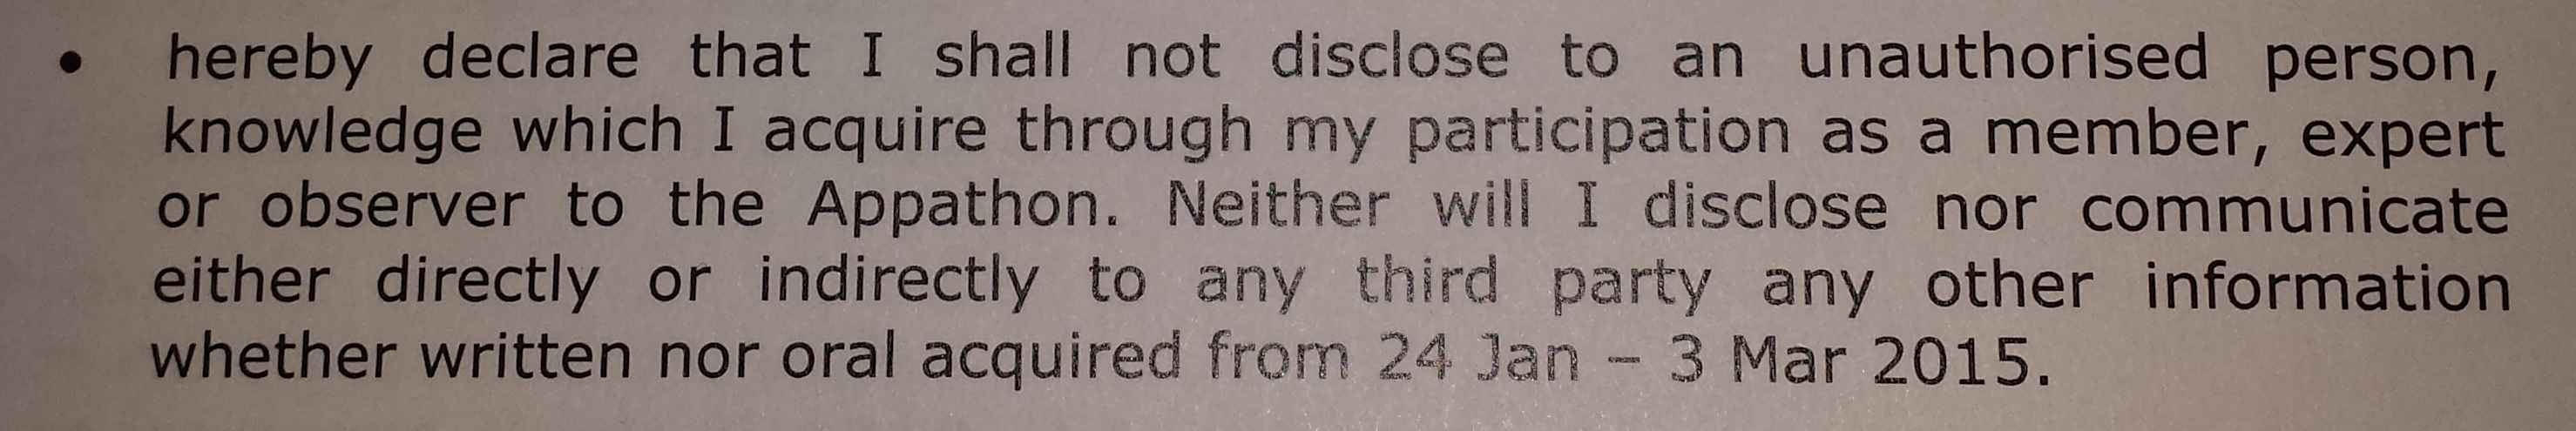
If you read the above text please leave your contact details in the comments so I can arrange to have somebody come round and shoot you.
In other news, I saw last week that the European Delegated Act requires that the European Space Agency to provide “Free and open access to Sentinel satellite data…” A requirement that is not incompatible with the wording above.
Empirical analysis of UK legislation started this weekend
Yesterday I was one of a dozen or so people at a hackathon hosted by the Ministry of Justice. I’m sure that the organizers would have liked a lot more people attending, but the McDonald’s hackathon across town was a bigger draw for most of the hackers I know.
The dataset was all UK legislation back to 1988, and a less complete set going back to 1267, in html and various flavors of xml; in all 20G of compressed files, with the compressed html files occupying 7G on my machine. As of this weekend the files are available online.
There were about half a dozen domain experts, in various aspects of the creation of UK legislation, present and they suggested lots of interesting questions that we (i.e., the attendees who could code) might like to try to answer.
I was surprised at the simplicity of some questions, e.g., volume (e.g., word count) of legislation over time and branch of government. The reason these question had not been answered before is that the data had not been available; empirical analysis of UK legislation started this weekend.
The most interesting question I heard involved the relative volume of primary and secondary legislation. Primary legislation is written by Parliament and in some cases creates a framework that is used by secondary legislation which contains the actual details. A lot of this secondary legislation is written by the Executive branch of government (by civil servants in the appropriate branch of government) and may not involve any parliamentary oversight. Comparing the relative volume of primary/secondary legislation over time would show if the Executive branch was gaining more powers to write laws, at the expense of Parliament.
With all the interesting discussions going on, setting ourselves up and copying the data (from memory sticks, not the internet), coding did not really start until 11, and we had to have our projects ‘handed-in’ by 16:00, not enough time to be sure of getting even an approximate answer to the primary/secondary legislation question. So I plumped for solving a simpler problem that I was confident of completing.
Certain phrases are known to be frequently used in legislation, e.g., “for the purposes of”. What phrases are actually very common in practice? The domain experts were interested in phrases by branch of government and other subsets; I decided to keep it simple by processing every file and giving them the data.
Counting sequences of n words is a very well studied problem and it was straightforward to locate a program to do it for me. I used the Lynx web browser to strip out the html (the importance of making raw text available for this kind of analysis work was recognized and this will be available at some future date). I decided that counting all four word sequences ought to be doable on my laptop and did manage to get it all to work in the available time. Code and list of 4-grams over the whole corpus available on Github.
As always, as soon as they saw the results, the domain experts immediately starting asking new questions.
Regular readers of this blog will know of my long standing involvement in the structure and interpretation of programming language standards. It was interesting to hear those involved in the writing/interpretation of legislation having exactly the same issues, and coming up with very similar solutions, as those of us in the language standards world. I was surprised to hear that UK legislation has switched from using “shall” to using “must” to express requirements (one of the hacks plotted the use of shall/must over time and there has been an abrupt change of usage). One of the reasons given was that “must” is more modern; no idea how word modernness was measured. In the ISO standards’ world “shall” is mandated over “must”. Everybody was very busy in the short amount of time available, so I had to leave an insiders chat about shall/must to another time.
The availability of such a large amount of structured English documents having great import should result in some interesting findings and tools being produced.
Predicting stuff involving the next hour of my life
Rain-on-me is an idea for an App that I have had for a while and have been trying to get people interested in it at Hackathons I attend. At the Techcrunch hackathon last weekend my pitch convinced Rob Finean, who I worked with at the Climate change hack, and we ended up winning in the Intel Mashery category (we used the wunderground API to get our realtime data).
The Rain-on-me idea is to use realtime rain data to predict how much rain will occur at my current location over the next hour or so (we divided the hour up into five minute intervals). This country, and others, has weather enthusiasts who operate their own weather stations and the data from these stations has been aggregated by the Weather Underground and made available on the Internet. Real-time data from local weather stations upwind of me could be used to predict what rain I am going to experience in the near future.
Anybody who has looked at weather station data, amateur or otherwise, knows that measured wind direction/speed can be surprisingly variable and that sometimes sensor stop reporting. But this is a hack, so lets be optimistic; station reporting intervals seem to be around 30 minutes, with some reporting every 15 mins and others once an hour, which is theory is good enough for our needs.
What really caught peoples’ attention was the simplicity of the user interface (try it and/or download code):
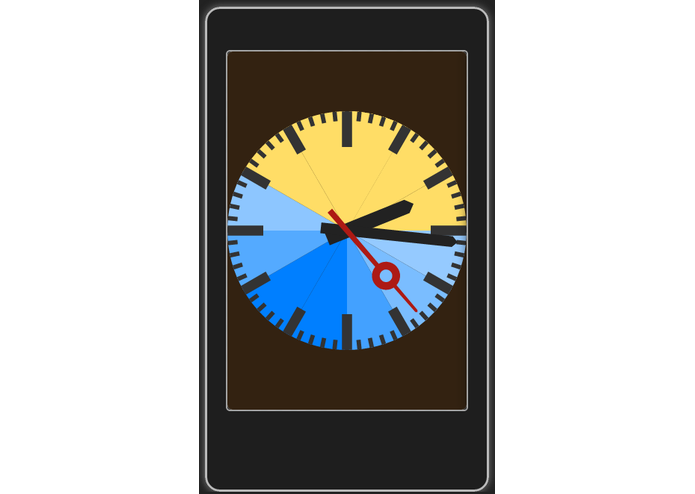
Being techies we were working on a design that showed quantity of rain and probability of occurring (this was early on and I had grand plans for modeling data from multiple stations). Rob had a circular plot design and Manoj (team member on previous hacks who has been bitten by the Raspberry pi bug) suggested designing it to run on a smart watch; my only contribution to the design was the use of five minute intervals.
The simplicity of the data presentation allows viewers to rapidly obtain a general idea of the rain situation in their location over the next hour (the hour is measured from the location of the minute hand; the shades of blue denote some combination of quantity of rain and probability of occurring).
This is the first App I’ve seen that actually makes sense on a smart watch. In fact if the watches communicated rain status at their current location then general accuracy over the next hour could become remarkably good.
Rainfall is only one of the things in my life that I would like predicted for the next hour. I want British rail to send me the predicted arrival time of the train I am on my way to catch (I may not need to rush so much if it is a few minutes late), when is the best time, in the next hour, to turn up at my barber for a hair cut (I want minimum waiting time after I arrive), average number of bikes for hire at my local docking station (should I leave now or is it safe to stay where I am a bit longer), etc.
Predicting events in the next hour of people’s lives is the future of Apps!
The existing rain-on-me implementation is very primitive; it uses the one weather station having the shortest perpendicular distance from the line going through the current location coming from the current wind direction (actually the App uses an hour of Saturday’s data since it was not raining on the Sunday lunchtime when we presented). There is plenty of room for improving the prediction reliability.
Other UK weather data sources include the UK Metoffice which supplies rainfall radar and rainfall predictions at hourly intervals for the next five days (presumably driven from the fancy whole Earth weather modeling they do); they also have an API for accessing hourly data from the 150 sites they operate.
The Weather Underground API is not particularly usable for this kind of problem. The call to obtain a list of stations close to a given latitude/longitude gives the distance (in miles and kilometers, isn’t there a formula to convert one to the other) of those station from what looks like the closest large town, so a separate call is needed for each station id to get their actual location!!! Rather late in the day I found out that the UK Metoffice has hidden away (or at least not obviously linked to) the Weather Observations Website which appears to be making available data from amateur weather stations.
Creating a map showing land covered by rising sea levels
I joined the Geekli.st climate Hackathon this weekend at the Hub Westminster (my favorite venue for Hackathons). While the organizers had lots of enthusiasm they had very little in the way of data for us to work on. No problem, ever since the Flood-relief hackathon I have wanted to use the SRTM ‘whole Earth’ elevation data on a flood related hack. Since this was a climate change related hack the obvious thing to do was to use the data to map the impact of any increases in sea level (try it, with wording for stronger believers).
The hacking officially started Friday evening at 19:00, but I only attended the evening event to meet people and form a team. Rob Finean was interested in the idea of mapping the effects of sea a rise in level (he also had previous experience using leaflet, a JavaScript library for interactive maps) and we formed a team, Florian Rathgeber joined us on Saturday morning.
I downloaded all the data for Eurasia (5.6G) when I got home Friday night and arriving back at the hackthon on Saturday morning started by writing a C program to convert the 5,876 files, each 1-degree by 1-degree squares on the surface of the Earth, to csv files.
The next step was to fit a mesh to the data and then locate constant altitude contours, at 0.5m and 1.5m above current sea level. Fitting a 2-D mesh to the data was easy (I wanted to use least squares rather than splines so that errors in the measurements could be taken into account), as was plotting and drawing contours, but getting the actual values for the contour lat/long proved to be elusive. I got bogged down looking at Python code, Florian knew a lot more Python than me and started looking for a Python solution while I investigated what R had to offer. Given the volume of data a Python solution looked like the best fit for the work-flow.
By late afternoon no real progress had been made and things were not looking good. Google searches on the obvious keywords returned lots of links to contour plotting libraries and papers claiming to have found a better contour evaluation algorithm, but no standalone libraries. I was reduced to downloading the source code of R to search for the code it used to calculate contours, with a view to extracting the code for my own use.
Rob wanted us to produce kml (Keyhole Markup Language) that his front end could read to render an overlay on a map.
At almost the same time Florian found that GDAL (Geospatial Data Abstraction Library) could convert hgt files (the raw SRTM file format) to kml and I discovered the R contourLines function. Florian had worked with GDAl before but having just completed his PhD had to leave to finish a paper he was working on, leaving us with instruction on the required options.
The kml output by GDAL was great for displaying contours, but did not fill in the enclosed area. The output I was generating using R filled the area enclosed by the contours but contained lots of noise because independent contours were treated having a connection to each other. I knew a script could be written to produce the desired output from the raw data, but did not know if GDAL had options to do what we wanted.
Its all very well being able to write a script to produce the desired output, but what is the desired output? Rob was able to figure out how the contour fill data had to be formatted in the kml file and I generated this using R, awk, sed, shell scripts and around six hours of cpu time on my laptop.
Rob’s front end uses leaflet with mapping data from Openstreetmap and the kml files to create a fantastic looking user-configurable map showing the effect of 0.5m and 1.5 rises in sea level.
The sea level data on the displayed map only shows the south of England and some of the north coast of Europe because loading any more results in poor performance (it is all loaded statically). Support is needed for dynamically loading of data on an as required basis. All of the kml files for Eurasia with 1.5 sea level rise are up on Github (900M+ of data). At the moment the contour data is only at the most detailed level of resolution and less detailed resolution is needed for when users zoom out. R’s contourLines function has no arguments for changing the resolution of which it returns; if you know of a better contour library please let me know.
The maps show average sea level. When tides are taken into account the sea level at certain times of the day may be a lot higher in some areas. We did not have access to tide data and would not have had time to make use of it anyway, so the effects of tide on sea level are not included.
Some of the speckling in the overlays may be noise caused by the error bounds of the SRTM data (around 6m for Eurasia; an accuracy level that makes our expectation of a difference between 0.5m and 1.5m contours problematic).
My first day developing for Google Glass
I was at the Google Glass Design Sprint & Workshop in London today. I don’t own a Google Glass and applied for one of the limited spaces available to developers who would be lent hardware for the day. Any idea I was harboring of Google recognizing me as an ace hackathon attendee were dashed at the start when we were told that the available slots had been filled by a random draw of applicants.
Vendor presentations at the start of hackathons tend to be either deadly dull or eye opening. Timothy Jordan explained why software written for Google Glass were not Apps, or rather should not be written with this mindset, but needed to be thought of in terms of enhancing the user’s experience in real time the moment; this really clicked with me. He also made some excellent points on user interface issues specific to the glass form factor which I think went over the head of most people present (this really needed its own slot).
I turned up with an App user enhancement experience reasonably well formed in my mind. The idea was to port the numbers tool to Android and have it scan the incoming camera image for numbers, information about the interesting ones being spoken into the users ear (e.g., that number of there is the rest mass of the electron).
On the day Google handled out a half a dozen brief biographies of potential Glass users and asked us to come up with ideas for software to enhance the lives of these people. I came up with the idea for helping the triathlete on the cycling leg of his competition. Having watched highlights from the Tour de France I knew that corners on the downhill stages of mountain routes presented a significant problem to riders traveling at up to 65 mph, i.e., how hard should they break to get safely around a corner whose curvature they could not see. My idea was for the corner curvature user experience to come to life when the riders speed exceeded, say, 45 mph and displayed a simple colored wiggly line that represented what lies around the bend.
Listening to other people at my table and in other groups I was surprised at how many were designing their idea as an App; that is, they wanted user to select from drop down menus and/or specify various numeric/literal values. My pointing out that they were designing Apps was met with blank stares.
Progress on writing actual code was hampered by lunch, having to leave at 17:30 and adb not working out of the box under Windows (this prevented any communication between the Android SDK running on Windows and Google glass). It took a while to figure out that the problem was adb/Windows (the Google folk had no idea it did not work since they all used Linux or Apple Macs). As usual an answer on Stackoverflow explained what changes needed to be made to the Google software. Asking around uncovered a few people with horror stories to tell about getting adb communication under Windows.
Microsoft Windows has significantly slipped in developer tool mind share over the last few years (I am even thinking of buying my first Mac next time I change my laptop). However, there are still a lot of Windows developers out there and Google will need to fix this problem if they want to attract lots and lots of developers.
But the biggest mistake Google need to fix is to make sure they don’t ever again run out of coffee mid-afternoon at an all day hackathon.
Recent Comments